Case study
Insolvency law. Unique precision: links to primary sources and semantic search.
Starting point
Insolvency lawyers need answers with sources, not piles of files. Case law and register filings are scattered, often scanned with a broken text layer. Generic language models answer confidently, but without the primary source. The domain was new to us, so we learned it first.
What we did
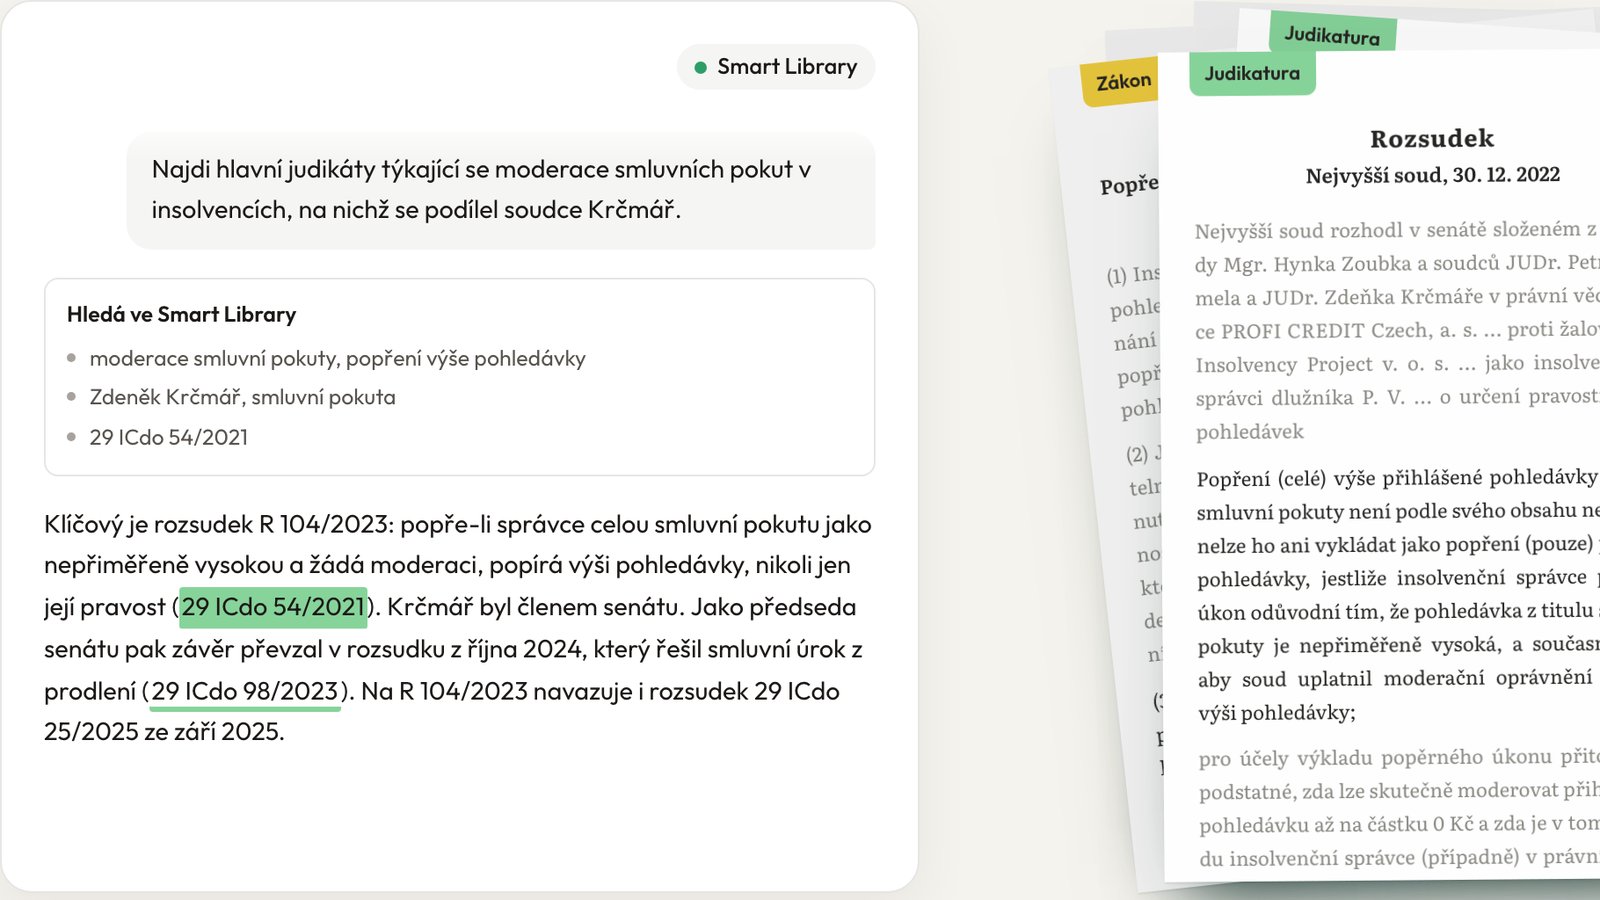
A knowledge base of Czech insolvency law: statutes from e-Sbírka, decisions of the Supreme, Constitutional, high and regional courts, and filings from the insolvency register. Ingestion repairs scanned and corrupted PDFs, with OCR where needed. Search works by meaning and by exact identifiers such as case numbers and sections. An answer may only use the retrieved passages, and every claim cites and opens the original at the highlighted spot. Multiple models behind one layer, with cost control.
The product is an MCP server: connect it to Claude or ChatGPT in two minutes, sign in with Google or Apple, 14 days free. For use without them, it has its own chat and document viewer.
Result
Over 100,000 documents as of October 2026: 5,135 Supreme Court decisions, 2,536 high and regional court decisions, 86,468 insolvency register filings, 228 monitored case files and 82 Constitutional Court findings. The MCP connector is submitted to the Claude and ChatGPT directories (11/2026). Demos with law firms are running.
Next step
Working on something similar?
An engineer replies within one business day. Within a week you have an honest view of scope, risk, and price.